


Weight-space programming means inspecting and directly modifying the numerical parameters of a neural network. Instead of asking a training optimizer to find an update, an agent can write code that measures internal behavior, constructs a specific change, and tests the resulting model. The weights retain that change when the next request arrives.
In the November 2026 Astra experiments, the released checkpoint, edit manifests, and investigation logs make this proposed model-repair workflow inspectable: we can connect the claimed improvement to the actual numbers changed. The release
Astra, the AI agent conducting the investigation, edited Qwen3.5-0.8B, a small language model. It modified another model’s weights, not its own.
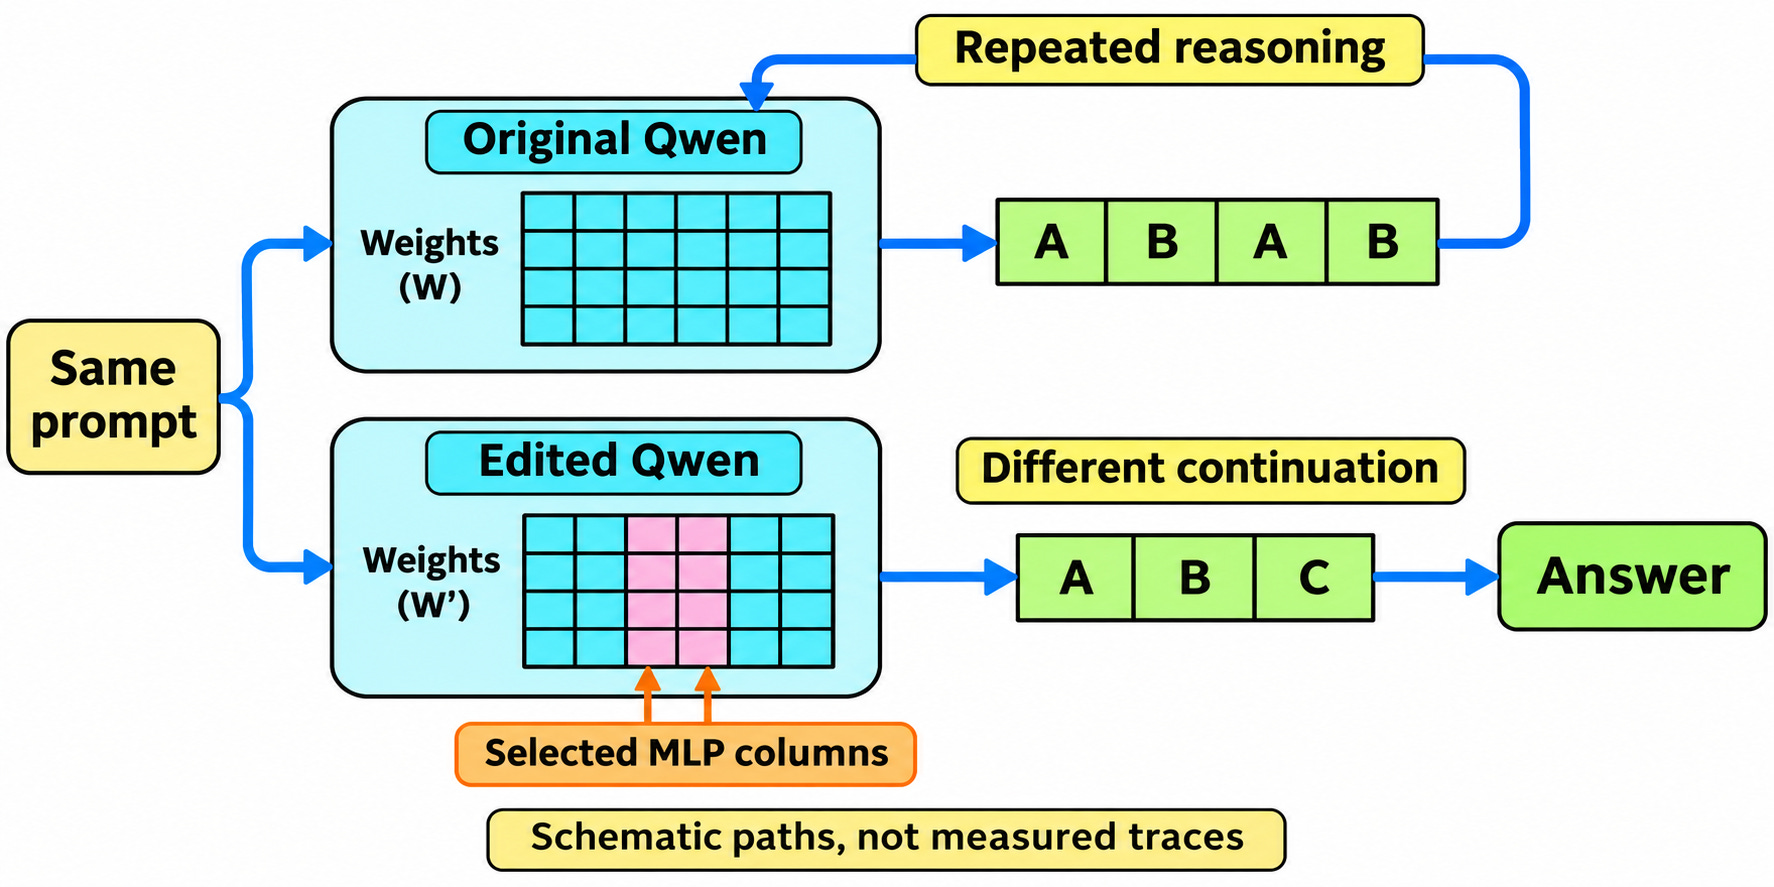
How could changing a small part of Qwen’s weights produce a large improvement?
The compact answer is that Astra changed what selected internal components contribute to Qwen’s working representation. Those contributions depend on the current input. The edited model consequently follows different generation paths, often escaping repetitive reasoning that previously consumed its entire output allowance.
The reported MATH-500 accuracy rose from 7.9% to 48.1%. Those figures average four generations for each of 500 questions; they are not the percentage of questions solved at least once. Under the same study settings, the share of generations hitting the 32,768-token limit fell from 93.0% to about 33.1%. Released evaluation results
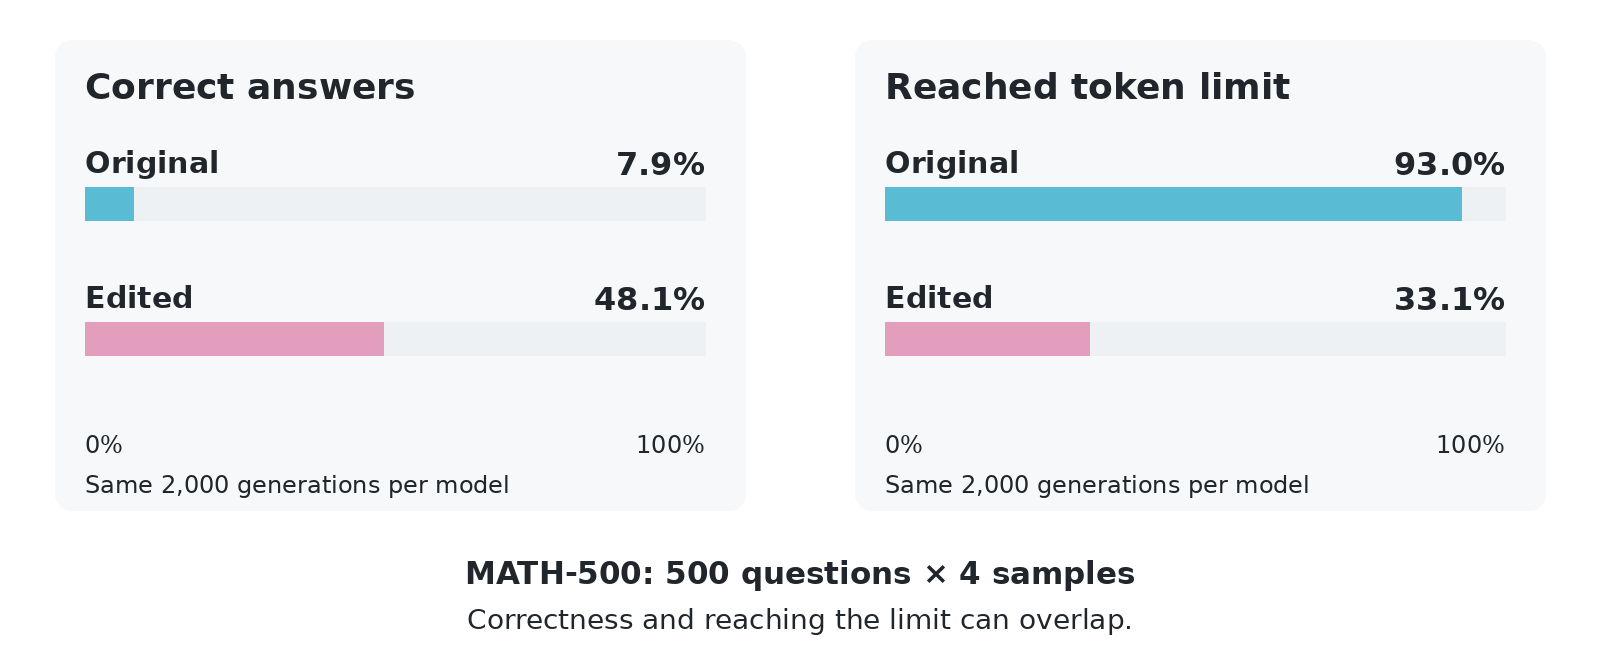
This gives us a useful first distinction. A math benchmark measures whether a run produces a correct, extractable answer under its evaluation conditions. A model that repeatedly restarts its reasoning can fail that test even when parts of its reasoning are useful. Changing how it continues can improve the measured score without establishing that new mathematical knowledge was inserted.
Accuracy and completion are also separate outcomes. A run can write the correct answer and then continue until the limit. We need both measurements, plus the actual intervention, to understand the result.
We will follow the computation from MLP columns to changed generations, then examine the controls, alternative generation settings, and requirements for reproduction.
Contents
What weight-space programming changes
How an MLP writes into a token state
How Astra found a candidate repair
What the final patch computes
Why generations changed
Which conclusions survive the controls
Reproduce the patch and test the claim
